Jonas Bauer · 15 October 2026
Examining Metadata Layering Effects on Discoverability Patterns Within Self-Managed Web Ecosystems
Self-managed web ecosystems consist of independently hosted sites that operate without reliance on centralized platforms, and metadata layering involves stacking multiple descriptive schemas, tags, and structured data formats on top of one another to enhance content description. Researchers have examined how these layers interact with crawler algorithms, and studies indicate that overlapping metadata can either amplify or obscure visibility signals depending on implementation consistency. Data from web indexing analyses show that sites using coordinated layers often experience improved crawl efficiency, while mismatched stacks lead to diluted priority in search results. Observers note that the process begins with basic HTML meta elements and extends through RDFa, JSON-LD, and custom vocabularies, creating a cumulative effect on how external systems parse and rank independent resources.
Core Components of Metadata Layering
Metadata layering starts with foundational elements such as title tags and description attributes, then builds outward through schema.org markup and Dublin Core extensions, while additional custom properties introduce site-specific context. Those who analyze server logs find that each successive layer adds processing overhead for crawlers, yet coordinated additions frequently improve semantic clarity across diverse content types. Evidence from indexing reports reveals that self-managed sites applying three or more aligned layers record higher rates of featured snippet inclusion compared to single-layer configurations. But the balance shifts when conflicting attributes appear, as duplicate property declarations prompt engines to deprioritize the entire resource stack. Patterns emerge in longitudinal data where sites maintained consistent layering across page templates and sustained steady traffic referral volumes over multi-year periods.
Discoverability Patterns Observed in Independent Environments
Discoverability within self-managed ecosystems follows distinct trajectories shaped by how metadata layers align with external knowledge graphs and link ecosystems. Analyses of crawl behavior demonstrate that layered metadata accelerates inclusion in specialized indexes when properties match established ontologies, whereas sparse or contradictory layers correlate with delayed or incomplete indexing. Figures from regional digital infrastructure surveys conducted through 2025 indicate that independent operators in North America and Europe who integrated progressive layering reported measurable gains in referral quality from academic and governmental domains. In October 2026, updates to major crawler guidelines emphasized validation of layered structures, prompting administrators to audit existing stacks for redundancy. What's notable is that sites incorporating geographic and temporal metadata attributes alongside core descriptive layers showed stronger retention in localized result sets, according to aggregated log data from multiple hosting providers.
Interaction with Search and Aggregation Systems
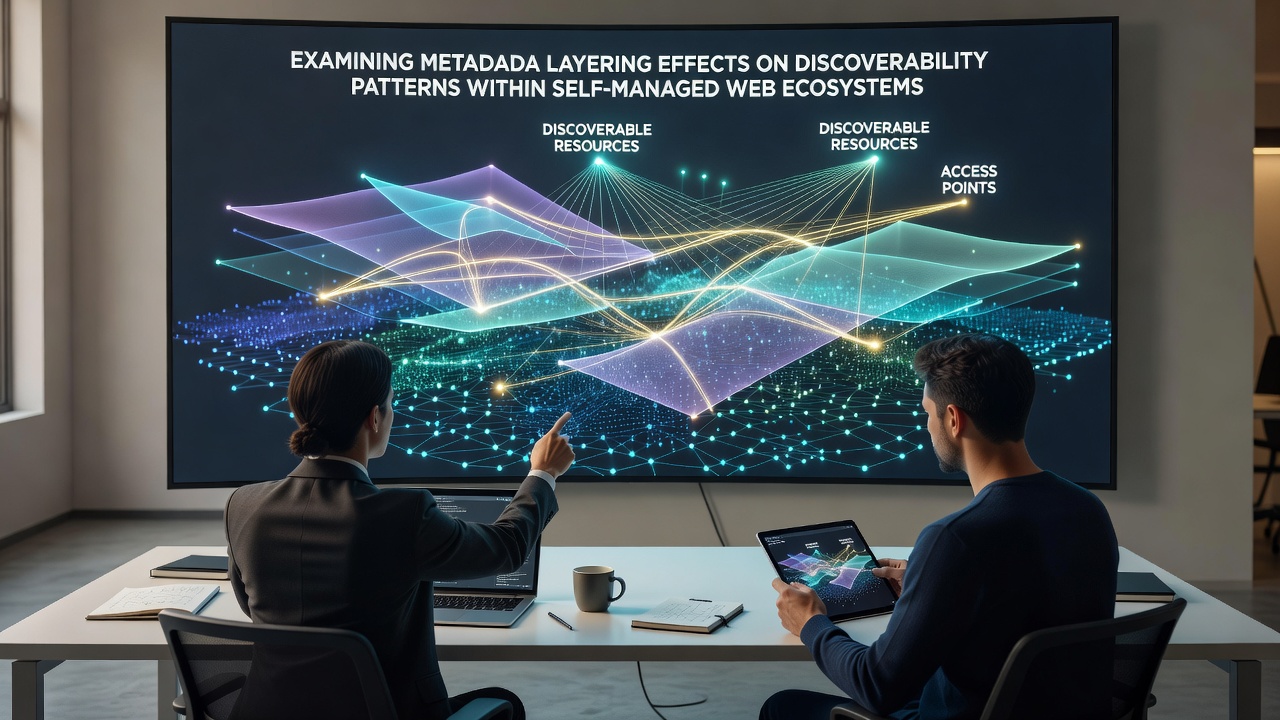
Search engines process layered metadata through successive validation passes that evaluate consistency, completeness, and relevance against query contexts. Research indicates that JSON-LD blocks nested within HTML documents interact with microdata attributes to form composite signals, and engines weigh these composites more heavily when they reinforce primary content themes. External aggregation services similarly parse layered structures to populate directories and recommendation engines, with alignment across layers increasing the probability of cross-platform syndication. Those examining traffic logs observe that self-managed sites with four or more synchronized layers maintain steadier inclusion rates during algorithm refreshes, while single-layer sites experience greater fluctuation. The reality is that layering effects compound over time as historical data feeds into ranking models, creating path dependencies that favor early adopters of structured approaches.
Empirical Data and Regional Variations
Quantitative assessments compiled from hosting analytics platforms reveal regional differences in how metadata layering influences discoverability outcomes. North American operators utilizing layered approaches alongside open data initiatives recorded higher referral percentages from educational repositories, while counterparts in Asia-Pacific regions noted stronger performance when layers incorporated multilingual attributes. According to documentation released by the World Wide Web Consortium, standardized layering practices reduce ambiguity in machine-readable descriptions and support broader interoperability across independent sites. Additional figures compiled by the OECD digital economy unit highlight that consistent metadata application correlates with improved visibility in cross-border search scenarios. Patterns in the data suggest that layering density reaches diminishing returns beyond a certain threshold, after which additional properties contribute minimal incremental gains unless they introduce novel contextual dimensions.
Implementation Factors and Maintenance Considerations
Successful metadata layering requires systematic validation routines that detect conflicts across schema versions and property namespaces. Administrators who implement automated checking tools report fewer instances of crawler misinterpretation, as inconsistent layers often trigger fallback behaviors that ignore advanced markup. Evidence from technical audits shows that self-managed environments benefit when layering protocols align with content update cycles, ensuring new pages inherit coherent structures rather than accumulating ad-hoc additions. Observers tracking long-term indexing trends find that periodic reviews of layered metadata prevent drift that could otherwise erode discoverability advantages built over previous periods. Coordination between template systems and metadata generators further stabilizes these effects, allowing independent operators to scale layering practices without proportional increases in manual oversight.
Conclusion
Metadata layering produces measurable effects on discoverability patterns across self-managed web ecosystems through its influence on crawler interpretation and external aggregation. Data compiled through 2026 demonstrates that aligned, multi-layer approaches enhance inclusion rates and referral stability when maintained consistently, while regional variations reflect differences in content focus and infrastructure support. Continued examination of these interactions provides operators with actionable insights derived from indexing behavior and traffic metrics, supporting informed decisions about metadata architecture in independent digital environments.